Blog Posts — Page 5
More articles on software, AI, and building useful things.
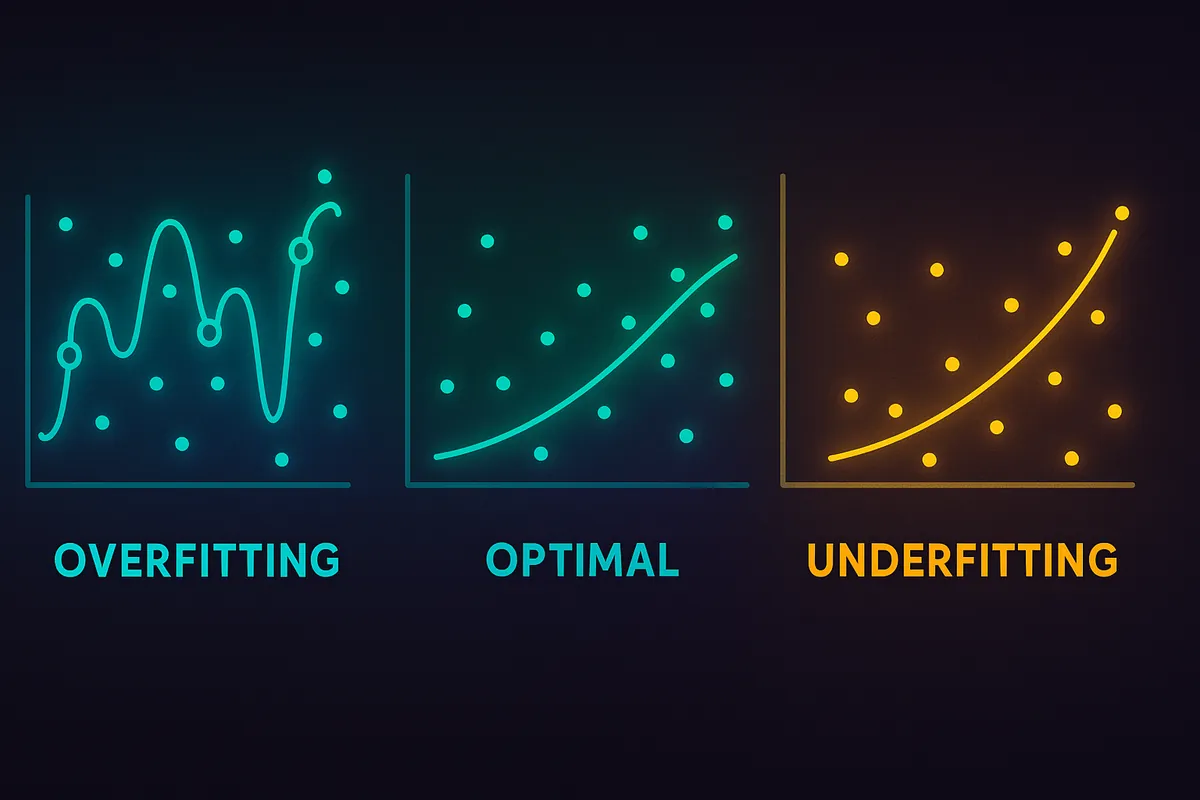
Overfitting vs. Underfitting: Reading Training and Validation Scores
Compare overfitting and underfitting through training and validation scores, then check data leakage, model capacity, and data quality before changing the model.
Choosing ML Algorithms: Build a Baseline Before Trying Six
A practical way to choose a machine-learning model: establish what a simple system achieves, then make complexity earn its place.
Unsupervised Learning: Your Clusters May Be Real, Their Names Are Your Invention
Unsupervised learning can reveal structure, but the distance measure, input scale, and interpretation still come from us.
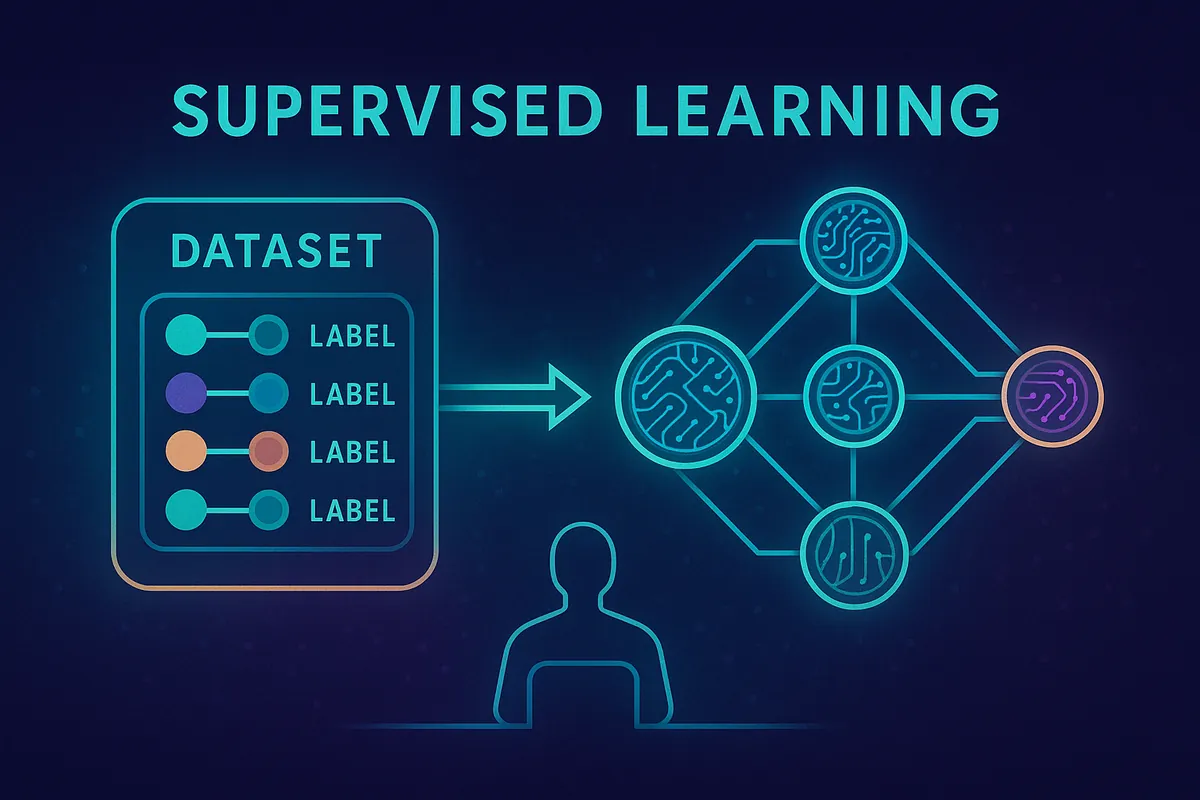
Supervised Learning with Labeled Data: Who Decides the Correct Answer?
Supervised learning depends on labeled examples. The difficult part is often deciding what those labels should mean.
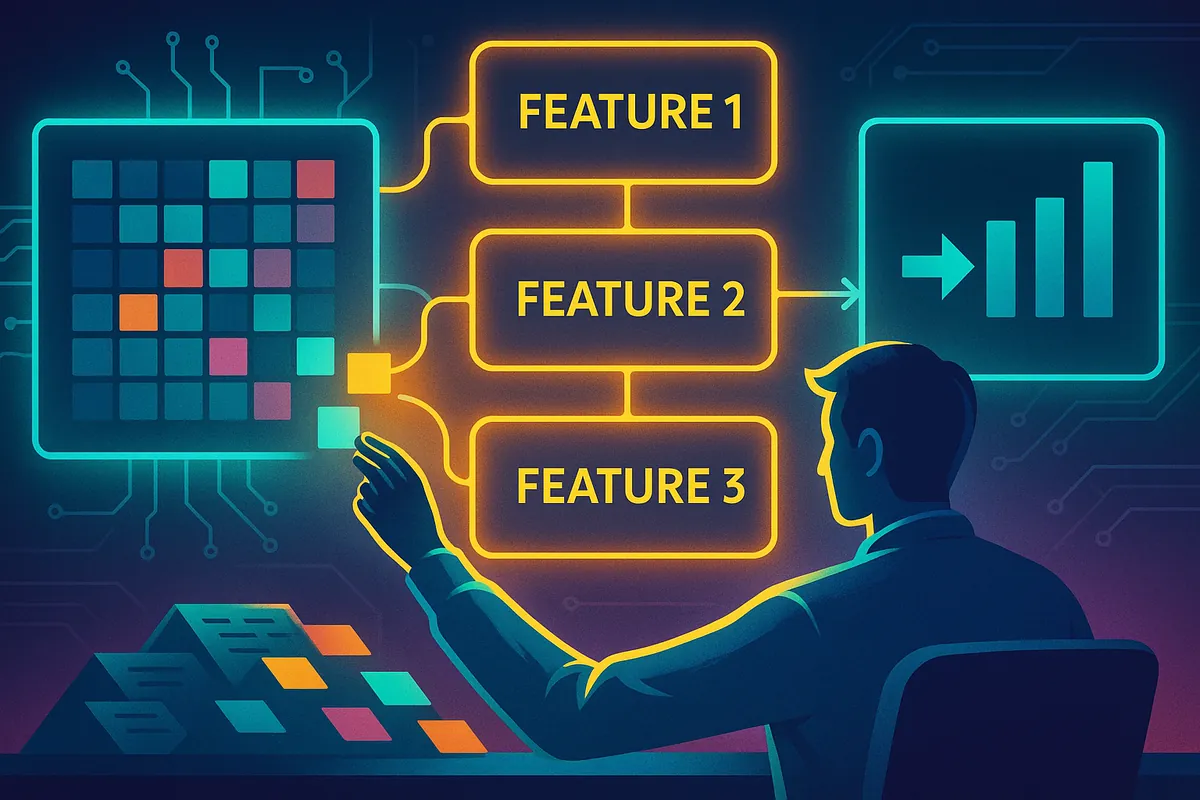
Feature Engineering: Your Best Feature Might Come from the Future
A delivery predictor explains why feature availability matters more than an impressive validation score.
Data Cleaning for ML: The Rows You Delete Are a Decision
Missing values, duplicates, and outliers are not interchangeable defects. A small delivery table shows why cleaning needs context.